Series 1 · 1 episode out
LLM inference through the lens of a GPU
One model (Qwen3.8-27B, BF16), one engine (vLLM 0.31), 1x NVIDIA H100 GPU. Each episode explains one idea with a number I measured, the source file it came from, and a Jupyter notebook that reproduces it.
Notebooks for every episode: tgarg01/Sillybench
Episode 1 · 18 Oct 2026
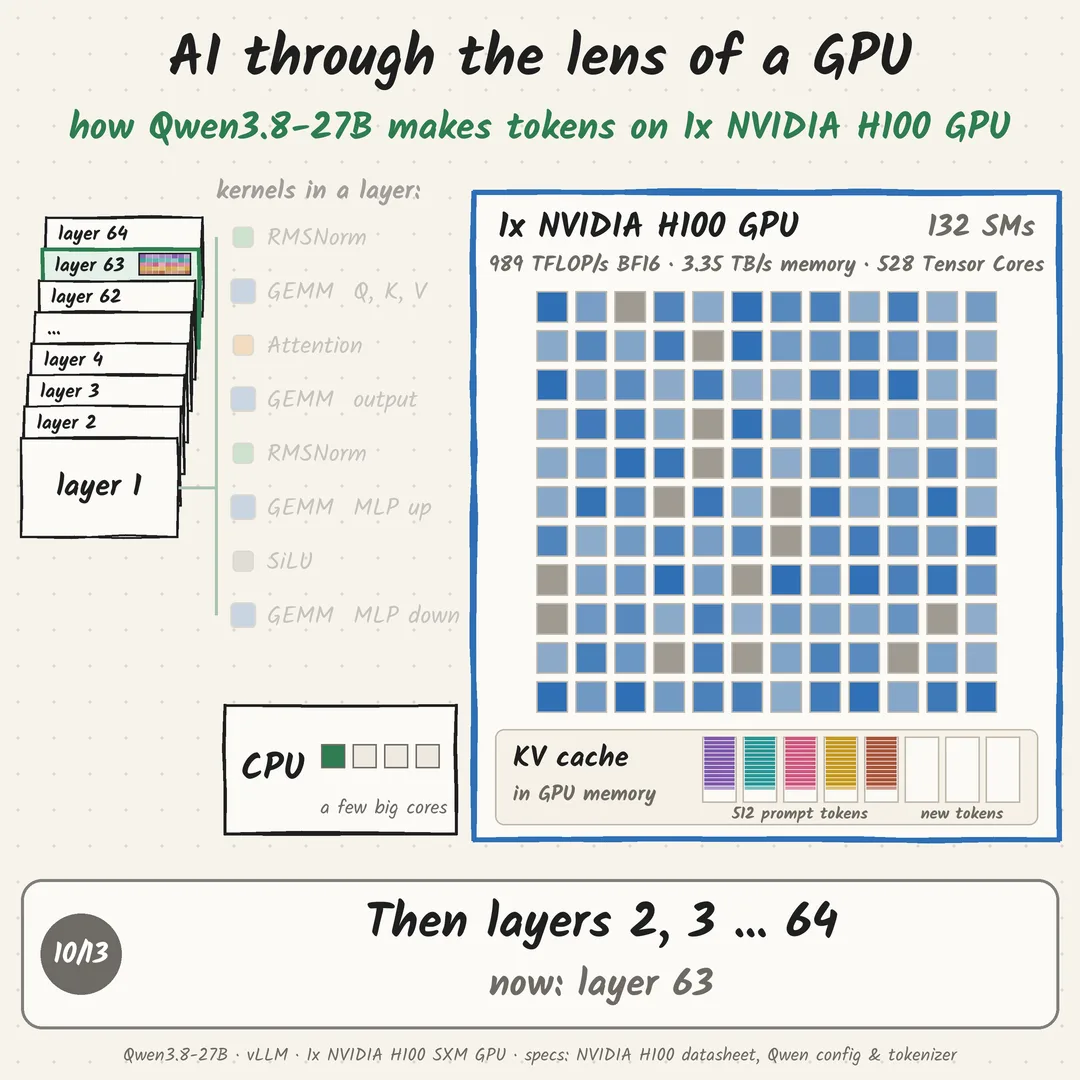
To 1x NVIDIA H100 GPU, Qwen3.8-27B isn't a model. It's a loop of 902 kernels.
What one decode step of Qwen3.8-27B looks like on 1x NVIDIA H100 GPU: 902 kernels in 20.55 ms, 92.6% of the GPU time in matrix multiplies. Measured with vLLM 0.31 and Nsight Systems.
Next episode · Thursday 22 Oct
Episode 2: Prefill vs Decode
Out on Thursday 22 Oct. Follow along on LinkedIn or RSS.
New episodes are added as the measurements come in.
Get the next episode
One email when a new episode is out, plus one figure that doesn’t fit on LinkedIn. No spam.